



 Chat with AI
Exam 17: Getting Ready to Analyze Data

Exam 1: Defining and Collecting Data202 Questions
Exam 2: Organizing and Visualizing256 Questions
Exam 3: Numerical Descriptive Measures217 Questions
Exam 4: Basic Probability167 Questions
Exam 5: Discrete Probability Distributions165 Questions
Exam 6: The Normal Distribution and Other Continuous Distributions170 Questions
Exam 7: Sampling Distributions165 Questions
Exam 8: Confidence Interval Estimation219 Questions
Exam 9: Fundamentals of Hypothesis Testing: One-Sample Tests194 Questions
Exam 10: Two-Sample Tests240 Questions
Exam 11: Analysis of Variance170 Questions
Exam 12: Chi-Square and Nonparametric188 Questions
Exam 13: Simple Linear Regression243 Questions
Exam 14: Introduction to Multiple394 Questions
Exam 15: Multiple Regression146 Questions
Exam 16: Time-Series Forecasting235 Questions
Exam 17: Getting Ready to Analyze Data386 Questions
Exam 18: Statistical Applications in Quality Management159 Questions
Exam 19: Decision Making126 Questions
Exam 20: Probability and Combinatorics421 Questions
Select questions type


Suppose the probability of a car accident taking place anywhere on a stretch of a 20 miles highway is the same. Which of the following distributions would you use to determine the
Probability that a car accident will occur somewhere between the 5-mile and 15-mile posts of the
Highway?
(Multiple Choice)
4.9/5  (81)
(81) SCENARIO 17-8
The superintendent of a school district wanted to predict the percentage of students passing a sixth-
grade proficiency test. She obtained the data on percentage of students passing the proficiency test
(% Passing), daily mean of the percentage of students attending class (% Attendance), mean teacher
salary in dollars (Salaries), and instructional spending per pupil in dollars (Spending) of 47 schools in
the state. Following is the multiple regression output with Passing as the dependent variable, Attendance, Salaries and Spending:
Regression Statistics Multiple R 0.7930 R Square 0.6288 Adjusted R 0.6029 Square Standard 10.4570 Error Observations 47
ANOVA
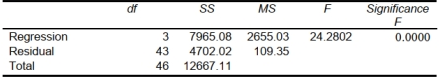 Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, there is sufficient evidence that the percentage of
students passing the proficiency test depends on all of the explanatory variables at a 5% level of
significance.
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, there is sufficient evidence that the percentage of
students passing the proficiency test depends on all of the explanatory variables at a 5% level of
significance. (True/False)
4.8/5 (88)
(88) The probability that a particular brand of smoke alarm will malfunction in the presence of smoke is 0.002. A batch of 100,000 such alarms was produced by independent production lines. Which
Of the following distributions would you use to figure out the probability that at most 5,000 of
Them will malfunction in case of a fire?
(Multiple Choice)
4.9/5 (78)
(78) A Paso Robles wine producer wanted to forecast the cases of Merlot wine sold. The number of cases of merlot wine sold in a 28-year period was collected. Which of the following would be the
Most appropriate analysis to perform?
(Multiple Choice)
4.7/5 (74)
(74) SCENARIO 17-11
A logistic regression model was estimated in order to predict the probability that a randomly chosen
university or college would be a private university using information on mean total Scholastic
Aptitude Test score (SAT) at the university or college, the room and board expense measured in
thousands of dollars (Room/Brd), and whether the TOEFL criterion is at least 550 (Toefl550 = 1 if
yes, 0 otherwise.) The dependent variable, Y, is school type (Type = 1 if private and 0 otherwise).
The Minitab output is given below: 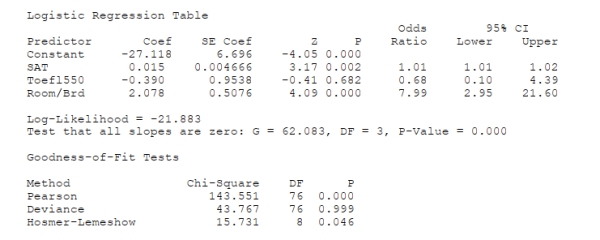 -Referring to Scenario 17-11, what should be the decision ('reject' or 'do not reject') on the null
hypothesis when testing whether Toefl500 makes a significant contribution to the model in the
presence of the other independent variables at a 0.05 level of significance?
-Referring to Scenario 17-11, what should be the decision ('reject' or 'do not reject') on the null
hypothesis when testing whether Toefl500 makes a significant contribution to the model in the
presence of the other independent variables at a 0.05 level of significance? (Short Answer)
5.0/5 (94)
(94) SCENARIO 17-15
The tree diagram below shows the results of the classification tree model that has been constructed to
predict the probability of a cable company's customers who will switch ("Yes" or "No") into its
bundled program offering based on the price ($30, $40, $50, $60) and whether the customer spends
more than 5 hours a day watching TV ("Yes" or "No") using the data set of 100 customers collected
from a survey. 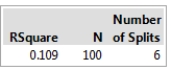
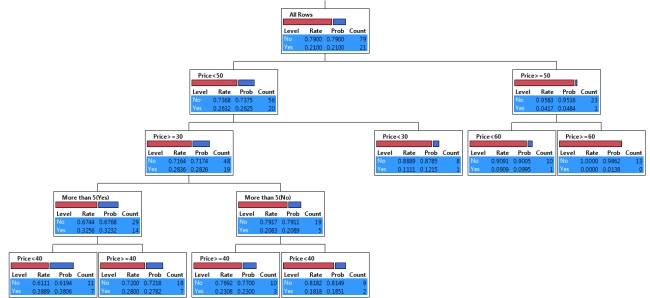 -Referring to Scenario 17-15, the highest probability of switching is predicted to
occur among customers who do not watch more than 5 hours of TV a day and are offered the
bundled price of higher than $50.
-Referring to Scenario 17-15, the highest probability of switching is predicted to
occur among customers who do not watch more than 5 hours of TV a day and are offered the
bundled price of higher than $50. (True/False)
4.7/5 (65)
(65) SCENARIO 17-10 Given below are results from the regression analysis where the dependent variable is the number of weeks a worker is unemployed due to a layoff (Unemploy) and the independent variables are the age of the worker (Age), the number of years of education received (Edu), the number of years at the previous job (Job Yr), a dummy variable for marital status (Married: married, otherwise), a dummy variable for head of household (Head: yes, no) and a dummy variable for management position (Manager: yes, no). We shall call this Model 1. The coefficient of partial determination ( (All raiables excopt ) ) of each of the 6 predictors are, respectively, , , and .
Regression Statistics Multiple R 0.7035 R Square 0.4949 Adjusted R 0.4030 Square Standard 18.4861 Error Observations 40
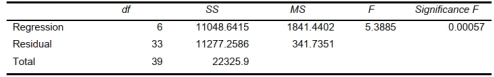 Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 32.6595 23.18302 1.4088 0.1683 -14.5067 79.8257 Age 1.2915 0.3599 3.5883 0.0011 0.5592 2.0238 Edu -1.3537 1.1766 -1.1504 0.2582 -3.7476 1.0402 Job Yr 0.6171 0.5940 1.0389 0.3064 -0.5914 1.8257 Married -5.2189 7.6068 -0.6861 0.4974 -20.6950 10.2571 Head -14.2978 7.6479 -1.8695 0.0704 -29.8575 1.2618 Manager -24.8203 11.6932 -2.1226 0.0414 -48.6102 -1.0303
-Referring to Scenario 17-10 Model 1, which of the following is the correct alternative hypothesis to determine whether there is a significant relationship between the number of weeks a
Worker is unemployed due to a layoff and the entire set of explanatory variables? a) : All for
b) : All for
c) : At least one of for
d) : At least one of for
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 32.6595 23.18302 1.4088 0.1683 -14.5067 79.8257 Age 1.2915 0.3599 3.5883 0.0011 0.5592 2.0238 Edu -1.3537 1.1766 -1.1504 0.2582 -3.7476 1.0402 Job Yr 0.6171 0.5940 1.0389 0.3064 -0.5914 1.8257 Married -5.2189 7.6068 -0.6861 0.4974 -20.6950 10.2571 Head -14.2978 7.6479 -1.8695 0.0704 -29.8575 1.2618 Manager -24.8203 11.6932 -2.1226 0.0414 -48.6102 -1.0303
-Referring to Scenario 17-10 Model 1, which of the following is the correct alternative hypothesis to determine whether there is a significant relationship between the number of weeks a
Worker is unemployed due to a layoff and the entire set of explanatory variables? a) : All for
b) : All for
c) : At least one of for
d) : At least one of for (Short Answer)
4.8/5 (76)
(76) SCENARIO 17-3 A financial analyst wanted to examine the relationship between salary (in ) and 4 variables: age , experience in the field Exper , number of degrees Degrees , and number of previous jobs in the field ( Prevjobs). He took a sample of 20 employees and obtained the following Microsoft Excel output:
SUMMARY OUTPUT
Regression Statistics Multiple R 0.992 R Square 0.984 Adjusted R Square 0.979 Standard Error 2.26743 Observations 20
df SS MS F Signif F Regression 4 4609.83164 1152.45791 224.160 0.0001 Residual 15 77.11836 5.14122 Total 19 4686.95000
Coeff StdError Stat P-value Intercept -9.611198 2.77988638 -3.457 0.0035 Age 1.327695 0.11491930 11.553 0.0001 Exper -0.106705 0.14265559 -0.748 0.4660 Degrees 7.311332 0.80324187 9.102 0.0001 Prevjobs -0.504168 0.44771573 -1.126 0.2778
-Referring to Scenario 17-3, the predicted salary for a 35-year-old person with 10 years of
experience, 3 degrees, and 1 previous job is ________.
(Short Answer)
4.9/5 (78)
(78) SCENARIO 17-8
The superintendent of a school district wanted to predict the percentage of students passing a sixth-
grade proficiency test. She obtained the data on percentage of students passing the proficiency test
(% Passing), daily mean of the percentage of students attending class (% Attendance), mean teacher
salary in dollars (Salaries), and instructional spending per pupil in dollars (Spending) of 47 schools in
the state. Following is the multiple regression output with Passing as the dependent variable, Attendance, Salaries and Spending:
Regression Statistics Multiple R 0.7930 R Square 0.6288 Adjusted R 0.6029 Square Standard 10.4570 Error Observations 47
ANOVA
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, the alternative hypothesis ,
3 implies that percentage of students passing the proficiency test is affected by all of the
explanatory variables.
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, the alternative hypothesis ,
3 implies that percentage of students passing the proficiency test is affected by all of the
explanatory variables. (True/False)
5.0/5 (67)
(67) In a classification tree, the dependent variable is a categorical variable.
(True/False)
4.8/5 (75)
(75) SCENARIO 17-8
The superintendent of a school district wanted to predict the percentage of students passing a sixth-
grade proficiency test. She obtained the data on percentage of students passing the proficiency test
(% Passing), daily mean of the percentage of students attending class (% Attendance), mean teacher
salary in dollars (Salaries), and instructional spending per pupil in dollars (Spending) of 47 schools in
the state. Following is the multiple regression output with Passing as the dependent variable, Attendance, Salaries and Spending:
Regression Statistics Multiple R 0.7930 R Square 0.6288 Adjusted R 0.6029 Square Standard 10.4570 Error Observations 47
ANOVA
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, the null hypothesis implies that percentage
of students passing the proficiency test is not affected by some of the explanatory variables.
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept -753.4225 101.1149 -7.4511 0.0000 -957.3401 -549.5050 \% Attendance 8.5014 1.0771 7.8929 0.0000 6.3292 10.6735 Salary 0.000000685 0.0006 0.0011 0.9991 -0.0013 0.0013 Spending 0.0060 0.0046 1.2879 0.2047 -0.0034 0.0153
-Referring to Scenario 17-8, the null hypothesis implies that percentage
of students passing the proficiency test is not affected by some of the explanatory variables. (True/False)
4.7/5 (83)
(83) SCENARIO 17-6
A weight-loss clinic wants to use regression analysis to build a model for weight-loss of a client
(measured in pounds). Two variables thought to affect weight-loss are client's length of time on the
weight loss program and time of session. These variables are described below: Y = Weight-loss (in pounds) = Length of time in weight-loss program (in months) =1 if morning session, 0 if not =1 if afternoon session, 0 if not (Base level = evening session)
Data for 12 clients on a weight-loss program at the clinic were collected and used to fit the interaction model:
Partial output from Microsoft Excel follows:
Regression Statistics Multiple R 0.73514 R Square 0.540438 Adjusted R Square 0.157469 Standard Error 12.4147 Observations 12
Coeff StdError t Stat P -value Intercept 0.089744 14.127 0.0060 0.9951 Length 6.22538 2.43473 2.54956 0.0479 Morn Ses 2.217272 22.1416 0.100141 0.9235 Aft Ses 11.8233 3.1545 3.558901 0.0165 Length*Morn Ses 0.77058 3.562 0.216334 0.8359 Length"Aft Ses -0.54147 3.35988 -0.161158 0.8773
-Referring to Scenario 17-6, the overall model for predicting weight-loss (Y) is
statistically significant at the 0.05 level.
(True/False)
4.7/5 (75)
(75) SCENARIO 17-12
The marketing manager for a nationally franchised lawn service company would like to study the
characteristics that differentiate home owners who do and do not have a lawn service. A random
sample of 30 home owners located in a suburban area near a large city was selected; 15 did not have
a lawn service (code 0) and 15 had a lawn service (code 1). Additional information available
concerning these 30 home owners includes family income (Income, in thousands of dollars), lawn
size (Lawn Size, in thousands of square feet), attitude toward outdoor recreational activities (Atitude 0
= unfavorable, 1 = favorable), number of teenagers in the household (Teenager), and age of the head
of the household (Age).
The Minitab output is given below: 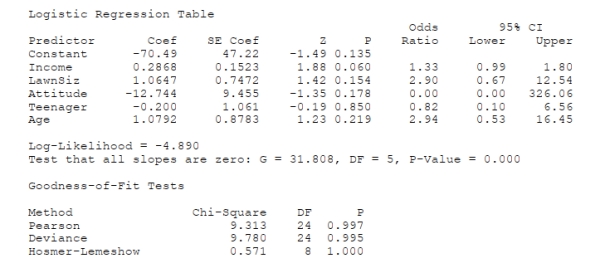 -Referring to Scenario 17-12, there is not enough evidence to conclude that
Income makes a significant contribution to the model in the presence of the other independent
variables at a 0.05 level of significance.
-Referring to Scenario 17-12, there is not enough evidence to conclude that
Income makes a significant contribution to the model in the presence of the other independent
variables at a 0.05 level of significance. (True/False)
4.8/5 (77)
(77) SCENARIO 17-12
The marketing manager for a nationally franchised lawn service company would like to study the
characteristics that differentiate home owners who do and do not have a lawn service. A random
sample of 30 home owners located in a suburban area near a large city was selected; 15 did not have
a lawn service (code 0) and 15 had a lawn service (code 1). Additional information available
concerning these 30 home owners includes family income (Income, in thousands of dollars), lawn
size (Lawn Size, in thousands of square feet), attitude toward outdoor recreational activities (Atitude 0
= unfavorable, 1 = favorable), number of teenagers in the household (Teenager), and age of the head
of the household (Age).
The Minitab output is given below:
-Referring to Scenario 17-12, what is the p-value of the test statistic when testing whether
Attitude makes a significant contribution to the model in the presence of the other independent
variables?
-Referring to Scenario 17-12, what is the p-value of the test statistic when testing whether
Attitude makes a significant contribution to the model in the presence of the other independent
variables? (Short Answer)
4.8/5 (75)
(75) Successful implementation of a classification tree requires rules for splitting the
data at each node based on a dependent variable.
(True/False)
5.0/5 (76)
(76) It was believed that the probability of a small business that declared bankruptcy per month was the same in any month. Also the number of small businesses that declared bankruptcy was the
Same every month. Which of the following distributions would you use to determine the
Probability that more than 3 bankruptcies will occur next month?
(Multiple Choice)
4.9/5 (76)
(76) A debate team of 4 members for a high school will be chosen randomly from a potential group of 15 students. Ten of the 15 students have no prior competition experience while the others have
Some degree of experience. Which of the following distributions would you use to determine the
Probability that none of the members chosen for the team have any competition experience?
(Multiple Choice)
4.7/5 (84)
(84) SCENARIO 17-2 One of the most common questions of prospective house buyers pertains to the cost of heating in dollars . To provide its customers with information on that matter, a large real estate firm used the following 4 variables to predict heating costs: the daily minimum outside temperature in degrees of Fahrenheit , the amount of insulation in inches , the number of windows in the house , and the age of the furnace in years . Given below are the EXCEL outputs of two regression models.
Model 1
Regression Statistics R Square 0.8080 Adjusted R Square 0.7568 Observations 20
df SS MS F Significance F Regression 4 169503.4241 42375.86 15.7874 0.0000 Residual 15 40262.3259 2684.155 Total 19 209765.75
Coefficients Standard Error t Stat P-value Lower 90.0\% Upper 90.0\% Intereept 421.4277 77.8614 5.4125 0.0000 284.9327 557.9227 (Temperature) -4.5098 0.8129 -5.5476 0.0000 -5.9349 -3.0847 (Insulation) -14.9029 5.0508 -2.9505 0.0099 -23.7573 -6.0485 (Windows) 0.2151 4.8675 0.0442 0.9653 -8.3181 8.7484 (Furnace Age) 6.3780 4.1026 1.5546 0.1408 -0.8140 13.5702
Regression Statistics R Square 0.7768 Adjusted R Square 0.7506 Observations 20
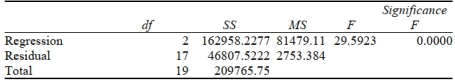 Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 489.3227 43.9826 11.1253 0.0000 396.5273 582.1180 (Temperature) -5.1103 0.6951 -7.3515 0.0000 -6.5769 -3.6437 (Insulation) -14.7195 4.8864 -3.0123 0.0078 -25.0290 -4.4099
-Referring to Scenario 17-2, what can we say about Model 1?
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 489.3227 43.9826 11.1253 0.0000 396.5273 582.1180 (Temperature) -5.1103 0.6951 -7.3515 0.0000 -6.5769 -3.6437 (Insulation) -14.7195 4.8864 -3.0123 0.0078 -25.0290 -4.4099
-Referring to Scenario 17-2, what can we say about Model 1? (Multiple Choice)
4.8/5 (82)
(82) SCENARIO 17-11
A logistic regression model was estimated in order to predict the probability that a randomly chosen
university or college would be a private university using information on mean total Scholastic
Aptitude Test score (SAT) at the university or college, the room and board expense measured in
thousands of dollars (Room/Brd), and whether the TOEFL criterion is at least 550 (Toefl550 = 1 if
yes, 0 otherwise.) The dependent variable, Y, is school type (Type = 1 if private and 0 otherwise).
The Minitab output is given below:
-Referring to Scenario 17-11, there is not enough evidence to conclude that
Toefl500 makes a significant contribution to the model in the presence of the other independent
variables at a 0.05 level of significance.
-Referring to Scenario 17-11, there is not enough evidence to conclude that
Toefl500 makes a significant contribution to the model in the presence of the other independent
variables at a 0.05 level of significance. (True/False)
4.8/5 (77)
(77) SCENARIO 17-10 Given below are results from the regression analysis where the dependent variable is the number of weeks a worker is unemployed due to a layoff (Unemploy) and the independent variables are the age of the worker (Age), the number of years of education received (Edu), the number of years at the previous job (Job Yr), a dummy variable for marital status (Married: married, otherwise), a dummy variable for head of household (Head: yes, no) and a dummy variable for management position (Manager: yes, no). We shall call this Model 1. The coefficient of partial determination ( (All raiables excopt ) ) of each of the 6 predictors are, respectively, , , and .
Regression Statistics Multiple R 0.7035 R Square 0.4949 Adjusted R 0.4030 Square Standard 18.4861 Error Observations 40
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 32.6595 23.18302 1.4088 0.1683 -14.5067 79.8257 Age 1.2915 0.3599 3.5883 0.0011 0.5592 2.0238 Edu -1.3537 1.1766 -1.1504 0.2582 -3.7476 1.0402 Job Yr 0.6171 0.5940 1.0389 0.3064 -0.5914 1.8257 Married -5.2189 7.6068 -0.6861 0.4974 -20.6950 10.2571 Head -14.2978 7.6479 -1.8695 0.0704 -29.8575 1.2618 Manager -24.8203 11.6932 -2.1226 0.0414 -48.6102 -1.0303
-Referring to Scenario 17-10 Model 1, what is the value of the test statistic to determine whether
there is a significant relationship between the number of weeks a worker is unemployed due to a
layoff and the entire set of explanatory variables?
Coefficients Standard Error t Stat P-value Lower 95\% Upper 95\% Intercept 32.6595 23.18302 1.4088 0.1683 -14.5067 79.8257 Age 1.2915 0.3599 3.5883 0.0011 0.5592 2.0238 Edu -1.3537 1.1766 -1.1504 0.2582 -3.7476 1.0402 Job Yr 0.6171 0.5940 1.0389 0.3064 -0.5914 1.8257 Married -5.2189 7.6068 -0.6861 0.4974 -20.6950 10.2571 Head -14.2978 7.6479 -1.8695 0.0704 -29.8575 1.2618 Manager -24.8203 11.6932 -2.1226 0.0414 -48.6102 -1.0303
-Referring to Scenario 17-10 Model 1, what is the value of the test statistic to determine whether
there is a significant relationship between the number of weeks a worker is unemployed due to a
layoff and the entire set of explanatory variables? (Short Answer)
5.0/5 (77)
(77) 
Filters
- Essay(0)
- Multiple Choice(0)
- Short Answer(0)
- True False(0)
- Matching(0)