



 Chat with AI
Exam 4: AWS Certified Data Analytics - Specialty (DAS-C01)

Exam 1: AWS Certified Advanced Networking - Specialty (ANS-C00)397 Questions
Exam 2: AWS Certified Alexa Skill Builder - Specialty68 Questions
Exam 3: AWS Certified Cloud Practitioner (CLF-C01)803 Questions
Exam 4: AWS Certified Data Analytics - Specialty (DAS-C01)135 Questions
Exam 5: AWS Certified Database - Specialty156 Questions
Exam 6: AWS Certified Developer Associate (DVA-C01)470 Questions
Exam 7: AWS Certified Machine Learning - Specialty (MLS-C01)159 Questions
Exam 8: AWS Certified Security - Specialty (SCS-C01)295 Questions
Exam 9: AWS Certified Solutions Architect - Associate SAA-C02596 Questions
Exam 10: AWS Certified Solutions Architect - Professional (SAP-C01)871 Questions
Exam 11: AWS Certified SysOps Administrator - Associate (SOA-C02)54 Questions
Exam 12: AWS DevOps Engineer - Professional (DOP-C01)610 Questions
Exam 13: AWS Certified SysOps Administrator (SOA-C01)976 Questions
Select questions type


A university intends to use Amazon Kinesis Data Firehose to collect JSON-formatted batches of water quality readings in Amazon S3. The readings are from 50 sensors scattered across a local lake. Students will query the stored data using Amazon Athena to observe changes in a captured metric over time, such as water temperature or acidity. Interest has grown in the study, prompting the university to reconsider how data will be stored. Which data format and partitioning choices will MOST significantly reduce costs? (Choose two.)
(Multiple Choice)
4.9/5  (67)
(67) A telecommunications company is looking for an anomaly-detection solution to identify fraudulent calls. The company currently uses Amazon Kinesis to stream voice call records in a JSON format from its on-premises database to Amazon S3. The existing dataset contains voice call records with 200 columns. To detect fraudulent calls, the solution would need to look at 5 of these columns only. The company is interested in a cost-effective solution using AWS that requires minimal effort and experience in anomaly-detection algorithms. Which solution meets these requirements?
(Multiple Choice)
4.9/5 (96)
(96) A manufacturing company uses Amazon Connect to manage its contact center and Salesforce to manage its customer relationship management (CRM) data. The data engineering team must build a pipeline to ingest data from the contact center and CRM system into a data lake that is built on Amazon S3. What is the MOST efficient way to collect data in the data lake with the LEAST operational overhead?
(Multiple Choice)
4.9/5 (80)
(80) A company's marketing team has asked for help in identifying a high performing long-term storage service for their data based on the following requirements: The data size is approximately 32 TB uncompressed. There is a low volume of single-row inserts each day. There is a high volume of aggregation queries each day. Multiple complex joins are performed. The queries typically involve a small subset of the columns in a table. Which storage service will provide the MOST performant solution?
(Multiple Choice)
4.8/5 (83)
(83) A streaming application is reading data from Amazon Kinesis Data Streams and immediately writing the data to an Amazon S3 bucket every 10 seconds. The application is reading data from hundreds of shards. The batch interval cannot be changed due to a separate requirement. The data is being accessed by Amazon Athena. Users are seeing degradation in query performance as time progresses. Which action can help improve query performance?
(Multiple Choice)
4.8/5 (67)
(67) An operations team notices that a few AWS Glue jobs for a given ETL application are failing. The AWS Glue jobs read a large number of small JSON files from an Amazon S3 bucket and write the data to a different S3 bucket in Apache Parquet format with no major transformations. Upon initial investigation, a data engineer notices the following error message in the History tab on the AWS Glue console: "Command Failed with Exit Code 1." Upon further investigation, the data engineer notices that the driver memory profile of the failed jobs crosses the safe threshold of 50% usage quickly and reaches 90-95% soon after. The average memory usage across all executors continues to be less than 4%. The data engineer also notices the following error while examining the related Amazon CloudWatch Logs. 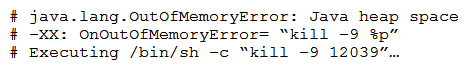 What should the data engineer do to solve the failure in the MOST cost-effective way?
 (Multiple Choice)
4.9/5 (70)
(70) A healthcare company uses AWS data and analytics tools to collect, ingest, and store electronic health record (EHR) data about its patients. The raw EHR data is stored in Amazon S3 in JSON format partitioned by hour, day, and year and is updated every hour. The company wants to maintain the data catalog and metadata in an AWS Glue Data Catalog to be able to access the data using Amazon Athena or Amazon Redshift Spectrum for analytics. When defining tables in the Data Catalog, the company has the following requirements: Choose the catalog table name and do not rely on the catalog table naming algorithm. Keep the table updated with new partitions loaded in the respective S3 bucket prefixes. Which solution meets these requirements with minimal effort?
(Multiple Choice)
4.9/5 (83)
(83) Three teams of data analysts use Apache Hive on an Amazon EMR cluster with the EMR File System (EMRFS) to query data stored within each teams Amazon S3 bucket. The EMR cluster has Kerberos enabled and is configured to authenticate users from the corporate Active Directory. The data is highly sensitive, so access must be limited to the members of each team. Which steps will satisfy the security requirements?
(Multiple Choice)
4.8/5 (78)
(78) A central government organization is collecting events from various internal applications using Amazon Managed Streaming for Apache Kafka (Amazon MSK). The organization has configured a separate Kafka topic for each application to separate the data. For security reasons, the Kafka cluster has been configured to only allow TLS encrypted data and it encrypts the data at rest. A recent application update showed that one of the applications was configured incorrectly, resulting in writing data to a Kafka topic that belongs to another application. This resulted in multiple errors in the analytics pipeline as data from different applications appeared on the same topic. After this incident, the organization wants to prevent applications from writing to a topic different than the one they should write to. Which solution meets these requirements with the least amount of effort?
(Multiple Choice)
5.0/5 (79)
(79) A large company has a central data lake to run analytics across different departments. Each department uses a separate AWS account and stores its data in an Amazon S3 bucket in that account. Each AWS account uses the AWS Glue Data Catalog as its data catalog. There are different data lake access requirements based on roles. Associate analysts should only have read access to their departmental data. Senior data analysts can have access in multiple departments including theirs, but for a subset of columns only. Which solution achieves these required access patterns to minimize costs and administrative tasks?
(Multiple Choice)
5.0/5 (86)
(86) A data analyst is designing a solution to interactively query datasets with SQL using a JDBC connection. Users will join data stored in Amazon S3 in Apache ORC format with data stored in Amazon Elasticsearch Service (Amazon ES) and Amazon Aurora MySQL. Which solution will provide the MOST up-to-date results?
(Multiple Choice)
4.8/5 (79)
(79) A company wants to provide its data analysts with uninterrupted access to the data in its Amazon Redshift cluster. All data is streamed to an Amazon S3 bucket with Amazon Kinesis Data Firehose. An AWS Glue job that is scheduled to run every 5 minutes issues a COPY command to move the data into Amazon Redshift. The amount of data delivered is uneven throughout the day, and cluster utilization is high during certain periods. The COPY command usually completes within a couple of seconds. However, when load spike occurs, locks can exist and data can be missed. Currently, the AWS Glue job is configured to run without retries, with timeout at 5 minutes and concurrency at 1. How should a data analytics specialist configure the AWS Glue job to optimize fault tolerance and improve data availability in the Amazon Redshift cluster?
(Multiple Choice)
4.8/5 (70)
(70) A software company hosts an application on AWS, and new features are released weekly. As part of the application testing process, a solution must be developed that analyzes logs from each Amazon EC2 instance to ensure that the application is working as expected after each deployment. The collection and analysis solution should be highly available with the ability to display new information with minimal delays. Which method should the company use to collect and analyze the logs?
(Multiple Choice)
4.8/5 (64)
(64) A company uses Amazon Redshift as its data warehouse. A new table has columns that contain sensitive data. The data in the table will eventually be referenced by several existing queries that run many times a day. A data analyst needs to load 100 billion rows of data into the new table. Before doing so, the data analyst must ensure that only members of the auditing group can read the columns containing sensitive data. How can the data analyst meet these requirements with the lowest maintenance overhead?
(Multiple Choice)
4.9/5 (77)
(77) A company is sending historical datasets to Amazon S3 for storage. A data engineer at the company wants to make these datasets available for analysis using Amazon Athena. The engineer also wants to encrypt the Athena query results in an S3 results location by using AWS solutions for encryption. The requirements for encrypting the query results are as follows: Use custom keys for encryption of the primary dataset query results. Use generic encryption for all other query results. Provide an audit trail for the primary dataset queries that shows when the keys were used and by whom. Which solution meets these requirements?
(Multiple Choice)
4.9/5 (78)
(78) A company has developed an Apache Hive script to batch process data stared in Amazon S3. The script needs to run once every day and store the output in Amazon S3. The company tested the script, and it completes within 30 minutes on a small local three-node cluster. Which solution is the MOST cost-effective for scheduling and executing the script?
(Multiple Choice)
5.0/5 (89)
(89) An airline has been collecting metrics on flight activities for analytics. A recently completed proof of concept demonstrates how the company provides insights to data analysts to improve on-time departures. The proof of concept used objects in Amazon S3, which contained the metrics in .csv format, and used Amazon Athena for querying the data. As the amount of data increases, the data analyst wants to optimize the storage solution to improve query performance. Which options should the data analyst use to improve performance as the data lake grows? (Choose three.)
(Multiple Choice)
4.9/5 (76)
(76) A banking company wants to collect large volumes of transactional data using Amazon Kinesis Data Streams for real-time analytics. The company uses PutRecord to send data to Amazon Kinesis, and has observed network outages during certain times of the day. The company wants to obtain exactly once semantics for the entire processing pipeline. What should the company do to obtain these characteristics?
(Multiple Choice)
4.8/5 (68)
(68) A hospital uses wearable medical sensor devices to collect data from patients. The hospital is architecting a near-real-time solution that can ingest the data securely at scale. The solution should also be able to remove the patient's protected health information (PHI) from the streaming data and store the data in durable storage. Which solution meets these requirements with the least operational overhead?
(Multiple Choice)
4.9/5 (79)
(79) A company's data analyst needs to ensure that queries executed in Amazon Athena cannot scan more than a prescribed amount of data for cost control purposes. Queries that exceed the prescribed threshold must be canceled immediately. What should the data analyst do to achieve this?
(Multiple Choice)
4.8/5 (89)
(89) 
Filters
- Essay(0)
- Multiple Choice(0)
- Short Answer(0)
- True False(0)
- Matching(0)