



 Chat with AI
Exam 4: AWS Certified Data Analytics - Specialty (DAS-C01)

Exam 1: AWS Certified Advanced Networking - Specialty (ANS-C00)397 Questions
Exam 2: AWS Certified Alexa Skill Builder - Specialty68 Questions
Exam 3: AWS Certified Cloud Practitioner (CLF-C01)803 Questions
Exam 4: AWS Certified Data Analytics - Specialty (DAS-C01)135 Questions
Exam 5: AWS Certified Database - Specialty156 Questions
Exam 6: AWS Certified Developer Associate (DVA-C01)470 Questions
Exam 7: AWS Certified Machine Learning - Specialty (MLS-C01)159 Questions
Exam 8: AWS Certified Security - Specialty (SCS-C01)295 Questions
Exam 9: AWS Certified Solutions Architect - Associate SAA-C02596 Questions
Exam 10: AWS Certified Solutions Architect - Professional (SAP-C01)871 Questions
Exam 11: AWS Certified SysOps Administrator - Associate (SOA-C02)54 Questions
Exam 12: AWS DevOps Engineer - Professional (DOP-C01)610 Questions
Exam 13: AWS Certified SysOps Administrator (SOA-C01)976 Questions
Select questions type


A data analytics specialist is setting up workload management in manual mode for an Amazon Redshift environment. The data analytics specialist is defining query monitoring rules to manage system performance and user experience of an Amazon Redshift cluster. Which elements must each query monitoring rule include?
(Multiple Choice)
4.8/5  (83)
(83) A retail company leverages Amazon Athena for ad-hoc queries against an AWS Glue Data Catalog. The data analytics team manages the data catalog and data access for the company. The data analytics team wants to separate queries and manage the cost of running those queries by different workloads and teams. Ideally, the data analysts want to group the queries run by different users within a team, store the query results in individual Amazon S3 buckets specific to each team, and enforce cost constraints on the queries run against the Data Catalog. Which solution meets these requirements?
(Multiple Choice)
4.9/5 (81)
(81) A bank operates in a regulated environment. The compliance requirements for the country in which the bank operates say that customer data for each state should only be accessible by the bank's employees located in the same state. Bank employees in one state should NOT be able to access data for customers who have provided a home address in a different state. The bank's marketing team has hired a data analyst to gather insights from customer data for a new campaign being launched in certain states. Currently, data linking each customer account to its home state is stored in a tabular .csv file within a single Amazon S3 folder in a private S3 bucket. The total size of the S3 folder is 2 GB uncompressed. Due to the country's compliance requirements, the marketing team is not able to access this folder. The data analyst is responsible for ensuring that the marketing team gets one-time access to customer data for their campaign analytics project, while being subject to all the compliance requirements and controls. Which solution should the data analyst implement to meet the desired requirements with the LEAST amount of setup effort?
(Multiple Choice)
4.8/5 (78)
(78) A company needs to store objects containing log data in JSON format. The objects are generated by eight applications running in AWS. Six of the applications generate a total of 500 KiB of data per second, and two of the applications can generate up to 2 MiB of data per second. A data engineer wants to implement a scalable solution to capture and store usage data in an Amazon S3 bucket. The usage data objects need to be reformatted, converted to .csv format, and then compressed before they are stored in Amazon S3. The company requires the solution to include the least custom code possible and has authorized the data engineer to request a service quota increase if needed. Which solution meets these requirements?
(Multiple Choice)
4.8/5 (89)
(89) An online retailer is rebuilding its inventory management system and inventory reordering system to automatically reorder products by using Amazon Kinesis Data Streams. The inventory management system uses the Kinesis Producer Library (KPL) to publish data to a stream. The inventory reordering system uses the Kinesis Client Library (KCL) to consume data from the stream. The stream has been configured to scale as needed. Just before production deployment, the retailer discovers that the inventory reordering system is receiving duplicated data. Which factors could be causing the duplicated data? (Choose two.)
(Multiple Choice)
4.9/5 (72)
(72) A manufacturing company uses Amazon S3 to store its data. The company wants to use AWS Lake Formation to provide granular-level security on those data assets. The data is in Apache Parquet format. The company has set a deadline for a consultant to build a data lake. How should the consultant create the MOST cost-effective solution that meets these requirements?
(Multiple Choice)
4.8/5 (86)
(86) An operations team notices that a few AWS Glue jobs for a given ETL application are failing. The AWS Glue jobs read a large number of small JOSN files from an Amazon S3 bucket and write the data to a different S3 bucket in Apache Parquet format with no major transformations. Upon initial investigation, a data engineer notices the following error message in the History tab on the AWS Glue console: "Command Failed with Exit Code 1." Upon further investigation, the data engineer notices that the driver memory profile of the failed jobs crosses the safe threshold of 50% usage quickly and reaches 90-95% soon after. The average memory usage across all executors continues to be less than 4%. The data engineer also notices the following error while examining the related Amazon CloudWatch Logs. 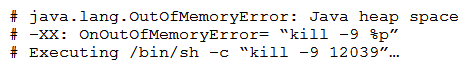 What should the data engineer do to solve the failure in the MOST cost-effective way?
 (Multiple Choice)
4.8/5 (82)
(82) A media content company has a streaming playback application. The company wants to collect and analyze the data to provide near-real-time feedback on playback issues. The company needs to consume this data and return results within 30 seconds according to the service-level agreement (SLA). The company needs the consumer to identify playback issues, such as quality during a specified timeframe. The data will be emitted as JSON and may change schemas over time. Which solution will allow the company to collect data for processing while meeting these requirements?
(Multiple Choice)
4.9/5 (95)
(95) A company operates toll services for highways across the country and collects data that is used to understand usage patterns. Analysts have requested the ability to run traffic reports in near-real time. The company is interested in building an ingestion pipeline that loads all the data into an Amazon Redshift cluster and alerts operations personnel when toll traffic for a particular toll station does not meet a specified threshold. Station data and the corresponding threshold values are stored in Amazon S3. Which approach is the MOST efficient way to meet these requirements?
(Multiple Choice)
4.7/5 (82)
(82) A large financial company is running its ETL process. Part of this process is to move data from Amazon S3 into an Amazon Redshift cluster. The company wants to use the most cost-efficient method to load the dataset into Amazon Redshift. Which combination of steps would meet these requirements? (Choose two.)
(Multiple Choice)
4.8/5 (71)
(71) A data analyst is using AWS Glue to organize, cleanse, validate, and format a 200 GB dataset. The data analyst triggered the job to run with the Standard worker type. After 3 hours, the AWS Glue job status is still RUNNING. Logs from the job run show no error codes. The data analyst wants to improve the job execution time without overprovisioning. Which actions should the data analyst take?
(Multiple Choice)
4.8/5 (78)
(78) A medical company has a system with sensor devices that read metrics and send them in real time to an Amazon Kinesis data stream. The Kinesis data stream has multiple shards. The company needs to calculate the average value of a numeric metric every second and set an alarm for whenever the value is above one threshold or below another threshold. The alarm must be sent to Amazon Simple Notification Service (Amazon SNS) in less than 30 seconds. Which architecture meets these requirements?
(Multiple Choice)
4.8/5 (82)
(82) A company has a marketing department and a finance department. The departments are storing data in Amazon S3 in their own AWS accounts in AWS Organizations. Both departments use AWS Lake Formation to catalog and secure their data. The departments have some databases and tables that share common names. The marketing department needs to securely access some tables from the finance department. Which two steps are required for this process? (Choose two.)
(Multiple Choice)
4.9/5 (71)
(71) A company wants to research user turnover by analyzing the past 3 months of user activities. With millions of users, 1.5 TB of uncompressed data is generated each day. A 30-node Amazon Redshift cluster with 2.56 TB of solid state drive (SSD) storage for each node is required to meet the query performance goals. The company wants to run an additional analysis on a year's worth of historical data to examine trends indicating which features are most popular. This analysis will be done once a week. What is the MOST cost-effective solution?
(Multiple Choice)
4.8/5 (76)
(76) A company currently uses Amazon Athena to query its global datasets. The regional data is stored in Amazon S3 in the us-east-1 and us-west-2 Regions. The data is not encrypted. To simplify the query process and manage it centrally, the company wants to use Athena in us-west-2 to query data from Amazon S3 in both Regions. The solution should be as low-cost as possible. What should the company do to achieve this goal?
(Multiple Choice)
4.9/5 (85)
(85) A company wants to improve user satisfaction for its smart home system by adding more features to its recommendation engine. Each sensor asynchronously pushes its nested JSON data into Amazon Kinesis Data Streams using the Kinesis Producer Library (KPL) in Java. Statistics from a set of failed sensors showed that, when a sensor is malfunctioning, its recorded data is not always sent to the cloud. The company needs a solution that offers near-real-time analytics on the data from the most updated sensors. Which solution enables the company to meet these requirements?
(Multiple Choice)
4.9/5 (79)
(79) A retail company's data analytics team recently created multiple product sales analysis dashboards for the average selling price per product using Amazon QuickSight. The dashboards were created from .csv files uploaded to Amazon S3. The team is now planning to share the dashboards with the respective external product owners by creating individual users in Amazon QuickSight. For compliance and governance reasons, restricting access is a key requirement. The product owners should view only their respective product analysis in the dashboard reports. Which approach should the data analytics team take to allow product owners to view only their products in the dashboard?
(Multiple Choice)
4.7/5 (84)
(84) A company is building a service to monitor fleets of vehicles. The company collects IoT data from a device in each vehicle and loads the data into Amazon Redshift in near-real time. Fleet owners upload .csv files containing vehicle reference data into Amazon S3 at different times throughout the day. A nightly process loads the vehicle reference data from Amazon S3 into Amazon Redshift. The company joins the IoT data from the device and the vehicle reference data to power reporting and dashboards. Fleet owners are frustrated by waiting a day for the dashboards to update. Which solution would provide the SHORTEST delay between uploading reference data to Amazon S3 and the change showing up in the owners' dashboards?
(Multiple Choice)
4.8/5 (78)
(78) A company analyzes its data in an Amazon Redshift data warehouse, which currently has a cluster of three dense storage nodes. Due to a recent business acquisition, the company needs to load an additional 4 TB of user data into Amazon Redshift. The engineering team will combine all the user data and apply complex calculations that require I/O intensive resources. The company needs to adjust the cluster's capacity to support the change in analytical and storage requirements. Which solution meets these requirements?
(Multiple Choice)
4.9/5 (84)
(84) A smart home automation company must efficiently ingest and process messages from various connected devices and sensors. The majority of these messages are comprised of a large number of small files. These messages are ingested using Amazon Kinesis Data Streams and sent to Amazon S3 using a Kinesis data stream consumer application. The Amazon S3 message data is then passed through a processing pipeline built on Amazon EMR running scheduled PySpark jobs. The data platform team manages data processing and is concerned about the efficiency and cost of downstream data processing. They want to continue to use PySpark. Which solution improves the efficiency of the data processing jobs and is well architected?
(Multiple Choice)
4.9/5 (75)
(75) 
Filters
- Essay(0)
- Multiple Choice(0)
- Short Answer(0)
- True False(0)
- Matching(0)