



 Chat with AI
Exam 7: AWS Certified Machine Learning - Specialty (MLS-C01)

Exam 1: AWS Certified Advanced Networking - Specialty (ANS-C00)397 Questions
Exam 2: AWS Certified Alexa Skill Builder - Specialty68 Questions
Exam 3: AWS Certified Cloud Practitioner (CLF-C01)803 Questions
Exam 4: AWS Certified Data Analytics - Specialty (DAS-C01)135 Questions
Exam 5: AWS Certified Database - Specialty156 Questions
Exam 6: AWS Certified Developer Associate (DVA-C01)470 Questions
Exam 7: AWS Certified Machine Learning - Specialty (MLS-C01)159 Questions
Exam 8: AWS Certified Security - Specialty (SCS-C01)295 Questions
Exam 9: AWS Certified Solutions Architect - Associate SAA-C02596 Questions
Exam 10: AWS Certified Solutions Architect - Professional (SAP-C01)871 Questions
Exam 11: AWS Certified SysOps Administrator - Associate (SOA-C02)54 Questions
Exam 12: AWS DevOps Engineer - Professional (DOP-C01)610 Questions
Exam 13: AWS Certified SysOps Administrator (SOA-C01)976 Questions
Select questions type


A Machine Learning team uses Amazon SageMaker to train an Apache MXNet handwritten digit classifier model using a research dataset. The team wants to receive a notification when the model is overfitting. Auditors want to view the Amazon SageMaker log activity report to ensure there are no unauthorized API calls. What should the Machine Learning team do to address the requirements with the least amount of code and fewest steps?
(Multiple Choice)
4.8/5  (84)
(84) A Machine Learning Specialist previously trained a logistic regression model using scikit-learn on a local machine, and the Specialist now wants to deploy it to production for inference only. What steps should be taken to ensure Amazon SageMaker can host a model that was trained locally?
(Multiple Choice)
4.9/5 (81)
(81) A retail chain has been ingesting purchasing records from its network of 20,000 stores to Amazon S3 using Amazon Kinesis Data Firehose. To support training an improved machine learning model, training records will require new but simple transformations, and some attributes will be combined. The model needs to be retrained daily. Given the large number of stores and the legacy data ingestion, which change will require the LEAST amount of development effort?
(Multiple Choice)
4.9/5 (72)
(72) A manufacturing company asks its machine learning specialist to develop a model that classifies defective parts into one of eight defect types. The company has provided roughly 100,000 images per defect type for training. During the initial training of the image classification model, the specialist notices that the validation accuracy is 80%, while the training accuracy is 90%. It is known that human-level performance for this type of image classification is around 90%. What should the specialist consider to fix this issue?
(Multiple Choice)
4.8/5 (86)
(86) A machine learning (ML) specialist is administering a production Amazon SageMaker endpoint with model monitoring configured. Amazon SageMaker Model Monitor detects violations on the SageMaker endpoint, so the ML specialist retrains the model with the latest dataset. This dataset is statistically representative of the current production traffic. The ML specialist notices that even after deploying the new SageMaker model and running the first monitoring job, the SageMaker endpoint still has violations. What should the ML specialist do to resolve the violations?
(Multiple Choice)
4.8/5 (80)
(80) A Data Scientist needs to analyze employment data. The dataset contains approximately 10 million observations on people across 10 different features. During the preliminary analysis, the Data Scientist notices that income and age distributions are not normal. While income levels shows a right skew as expected, with fewer individuals having a higher income, the age distribution also shows a right skew, with fewer older individuals participating in the workforce. Which feature transformations can the Data Scientist apply to fix the incorrectly skewed data? (Choose two.)
(Multiple Choice)
5.0/5 (76)
(76) A company wants to classify user behavior as either fraudulent or normal. Based on internal research, a machine learning specialist will build a binary classifier based on two features: age of account, denoted by x, and transaction month, denoted by y. The class distributions are illustrated in the provided figure. The positive class is portrayed in red, while the negative class is portrayed in black. 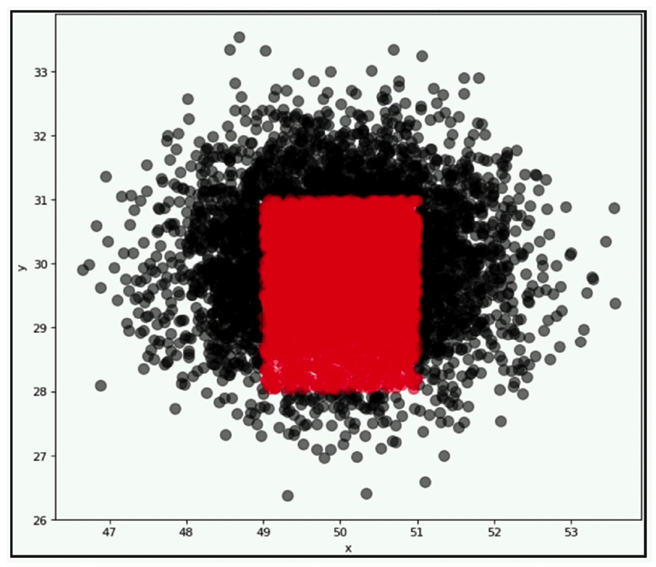 Which model would have the HIGHEST accuracy?
 (Multiple Choice)
4.9/5 (80)
(80) A Machine Learning Specialist built an image classification deep learning model. However, the Specialist ran into an overfitting problem in which the training and testing accuracies were 99% and 75%, respectively. How should the Specialist address this issue and what is the reason behind it?
(Multiple Choice)
4.8/5 (78)
(78) A company uses camera images of the tops of items displayed on store shelves to determine which items were removed and which ones still remain. After several hours of data labeling, the company has a total of 1,000 hand-labeled images covering 10 distinct items. The training results were poor. Which machine learning approach fulfills the company's long-term needs?
(Multiple Choice)
4.9/5 (73)
(73) A data science team is planning to build a natural language processing (NLP) application. The application's text preprocessing stage will include part-of-speech tagging and key phase extraction. The preprocessed text will be input to a custom classification algorithm that the data science team has already written and trained using Apache MXNet. Which solution can the team build MOST quickly to meet these requirements?
(Multiple Choice)
4.8/5 (81)
(81) A health care company is planning to use neural networks to classify their X-ray images into normal and abnormal classes. The labeled data is divided into a training set of 1,000 images and a test set of 200 images. The initial training of a neural network model with 50 hidden layers yielded 99% accuracy on the training set, but only 55% accuracy on the test set. What changes should the Specialist consider to solve this issue? (Choose three.)
(Multiple Choice)
4.8/5 (91)
(91) A Data Scientist needs to create a serverless ingestion and analytics solution for high-velocity, real-time streaming data. The ingestion process must buffer and convert incoming records from JSON to a query-optimized, columnar format without data loss. The output datastore must be highly available, and Analysts must be able to run SQL queries against the data and connect to existing business intelligence dashboards. Which solution should the Data Scientist build to satisfy the requirements?
(Multiple Choice)
4.8/5 (95)
(95) A Machine Learning Specialist is training a model to identify the make and model of vehicles in images. The Specialist wants to use transfer learning and an existing model trained on images of general objects. The Specialist collated a large custom dataset of pictures containing different vehicle makes and models. What should the Specialist do to initialize the model to re-train it with the custom data?
(Multiple Choice)
4.9/5 (64)
(64) A retail company wants to combine its customer orders with the product description data from its product catalog. The structure and format of the records in each dataset is different. A data analyst tried to use a spreadsheet to combine the datasets, but the effort resulted in duplicate records and records that were not properly combined. The company needs a solution that it can use to combine similar records from the two datasets and remove any duplicates. Which solution will meet these requirements?
(Multiple Choice)
4.8/5 (75)
(75) A Machine Learning Specialist at a company sensitive to security is preparing a dataset for model training. The dataset is stored in Amazon S3 and contains Personally Identifiable Information (PII). The dataset: Must be accessible from a VPC only. Must not traverse the public internet. How can these requirements be satisfied?
(Multiple Choice)
5.0/5 (87)
(87) A Machine Learning Specialist is working for an online retailer that wants to run analytics on every customer visit, processed through a machine learning pipeline. The data needs to be ingested by Amazon Kinesis Data Streams at up to 100 transactions per second, and the JSON data blob is 100 KB in size. What is the MINIMUM number of shards in Kinesis Data Streams the Specialist should use to successfully ingest this data?
(Multiple Choice)
5.0/5 (70)
(70) A Machine Learning Specialist is developing a daily ETL workflow containing multiple ETL jobs. The workflow consists of the following processes: • Start the workflow as soon as data is uploaded to Amazon S3. • When all the datasets are available in Amazon S3, start an ETL job to join the uploaded datasets with multiple terabyte-sized datasets already stored in Amazon S3. • Store the results of joining datasets in Amazon S3. • If one of the jobs fails, send a notification to the Administrator. Which configuration will meet these requirements?
(Multiple Choice)
4.8/5 (91)
(91) A Machine Learning Specialist needs to move and transform data in preparation for training. Some of the data needs to be processed in near-real time, and other data can be moved hourly. There are existing Amazon EMR MapReduce jobs to clean and feature engineering to perform on the data. Which of the following services can feed data to the MapReduce jobs? (Choose two.)
(Multiple Choice)
4.9/5 (79)
(79) A company sells thousands of products on a public website and wants to automatically identify products with potential durability problems. The company has 1.000 reviews with date, star rating, review text, review summary, and customer email fields, but many reviews are incomplete and have empty fields. Each review has already been labeled with the correct durability result. A machine learning specialist must train a model to identify reviews expressing concerns over product durability. The first model needs to be trained and ready to review in 2 days. What is the MOST direct approach to solve this problem within 2 days?
(Multiple Choice)
5.0/5 (90)
(90) A financial company is trying to detect credit card fraud. The company observed that, on average, 2% of credit card transactions were fraudulent. A data scientist trained a classifier on a year's worth of credit card transactions data. The model needs to identify the fraudulent transactions (positives) from the regular ones (negatives). The company's goal is to accurately capture as many positives as possible. Which metrics should the data scientist use to optimize the model? (Choose two.)
(Multiple Choice)
4.8/5 (85)
(85) 
Filters
- Essay(0)
- Multiple Choice(0)
- Short Answer(0)
- True False(0)
- Matching(0)